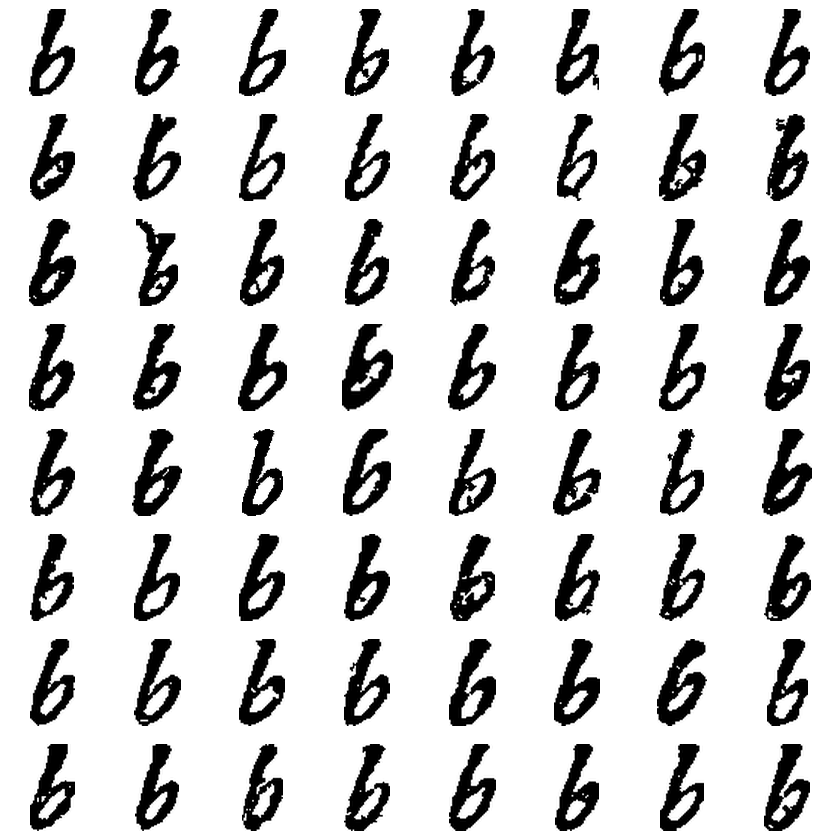
The short version
Gallup’s decipherment rests on a step that comes before any decoding: somebody has to look at each italic letter on the page and put it in one of two boxes. Today asked two questions about that step. Where did she say how to do it? And can it be done at all — by anyone, including a machine with no opinion about Bacon?
The first question has a documentary answer, and it is sharper than expected. The second now has a measured one, with the measurement’s own limits stated alongside it.
Questions
What is the biliteral cipher?
Sir Francis Bacon described it in 1623. Every letter becomes a group of five symbols, each symbol either an a or a b — five binary digits, three hundred years before anyone called them that. AAAAA is A, AAAAB is B, and so on.
The two symbols need not be letters. They can be two founts of type so similar that a reader notices nothing. Print an innocent passage in an alternating mixture of the two and it carries a second message, readable only by someone who can tell the founts apart. The system is sound; nothing here disputes it.
So what is actually being tested?
Not the cipher. The sorting.
Before a single letter of hidden message can be read, every italic letter on the page must be assigned to one of two founts. Gallup did that by eye, on four-hundred-year-old printing, alone. If the two founts are really there and really distinguishable, then a measurement made on clean images of those letters should find two groups. That is a necessary condition — it does not prove a message exists, but without it nothing else can follow.
Today that test was run properly for the first time in this project: on one letter, with the instrument’s sensitivity measured rather than assumed.
Where did Gallup explain how to tell the two founts apart?
Essentially nowhere, and this is the day’s documentary finding.
Her 1901 third edition runs to 463 pages in two sequences — 95 pages of front matter and 368 of decipherment. The whole of the front matter offers one sentence of guidance, on page 2, and it names no feature of any letter. She writes that the distinguishing marks in the small letters have been difficult to classify, and that close study is needed to “educate the eye to distinguish them.”
The section that sounds as though it should hold the method — Bi-literal Cipher Plan and Illustration, page 51 — turns out to be Bacon’s own a/b alphabet table. That tells you how a string of a’s and b’s becomes a letter. It says nothing about how to decide whether a given piece of printed ink is an a or a b. Those are different problems, and only the second one is hard.
The terms a-form and b-form do not appear anywhere in the volume.
Then where does the method come from?
From Riverbank, in 1916 — fifteen years after the results it would govern were published. A short monograph called Hints to the Decipherer gives the only feature-level description that exists, and it names five things, not one:
The a-form letters are “larger, rounder, more upright, and more robust” than the b-forms. And of the long-tailed letters — which includes b — the b-form “usually slopes more and has longer flourishes.”
That is a testable specification, and it is the one today’s work was measured against. It is worth being plain about the order of events: the results were published first and the method described afterwards, by other people, once Fabyan had staff who needed to be taught to replicate her.
What did you find?
In 149 clean images of the letter b, nothing that separates them into two groups.
The search was deliberately ignorant — it was not told what a b is, that two forms are claimed, or what to look for. It looked for whatever split the set best. On a fair test, where the rule is found on half the glyphs and then scored on the other half, it succeeded once in 36 attempts. Randomly chosen rules did about as well.
What makes that meaningful rather than empty is the calibration. The same search, given a difference that really was there, found it: a 7% difference in size, a 13% difference in tail length, a 6-degree difference in slant. So the absence of a result places a ceiling on how big any real difference could be and still have escaped notice.
Does that prove Gallup was wrong?
No. It is one letter, from 41 pages, under one instrument, and it bounds rather than refutes.
Three honest limits. The corpus is small — 149 letters is enough to catch a 6-degree difference but not a 3-degree one. It is one letter of the alphabet, and Riverbank’s rules differ by letter shape. And two of their five characteristics were not tested at all, because the method could not see them.
What the day does establish is narrower and firmer: for size, tail length and slant, any real difference between two forms of b in these pages is smaller than the figures above. That is a number where before there was an argument.
What would change your mind?
Stated before the result, as always, and unchanged by it:
A measurement that splits a large set of one letter into two groups, found on part of the data and still working on part it has never seen — and surviving the same test when the labels are shuffled. Or, more directly: Gallup’s own published assignment for specific glyphs on specific pages, so that a rule can be trained on part of her classification and tested on the rest. If her sorting is reproducible, that test will show it, and it is roughly three times more sensitive than searching blind.
Today’s negative result is an argument for getting those labels, not against it.
Why only one letter, and why b?
Because a mixed bag of letters cannot be tested. Two b’s can be compared; a b and an o differ for reasons that have nothing to do with any cipher. Riverbank’s own rules are stated per letter shape, which confirms the point.
b was chosen because it is a long-tailed letter, so Riverbank’s most specific rule applies to it; because it has an enclosed bowl, which gives an independent quality check; and because they printed two b exemplars of their own, which could be used to screen the corpus without appealing to anything they claimed about the two forms.
Who is doing this, and why?
Walter Wilkinson, in Worland, Wyoming, working with a computer and free scans. There is no institution behind this and no funding.
The aim is not to prove or disprove that Bacon wrote Shakespeare. It is to find out whether the specific evidence offered for the biliteral decipherment can carry the weight placed on it — and to publish the answer in the same terms whichever way it falls. Today it fell against the claim, and it is reported exactly as a positive would have been.
More at New Gorhambury, and at Experiment One. Experiment One argues a conclusion; these reports deliberately do not.
External documents
Every source relied on today, with what it is, what you would find there, and what it is doing in this issue. The link comes last on purpose.
Technical colophon
Prior know-how is assumed, and the items become more “technical” toward the bottom.
This issue was produced on 11 October 2026. It is image work, not text work: 174 glyphs were cut from 41 Folio pages, screened, and put to a blind separator-finder whose sensitivity was measured rather than assumed. Every figure below can be recomputed from the corpus and scripts published with the issue.
⚑ Where the volume actually says anything
Gallup 1901 is catalogued “95, 368 p.” — two sequences. Part I’s contents, in full: Personal 1, Explanatory Introduction 5, Preface to the Second Edition 15, Argument 18, Notes on the Shakespeare Plays 28, Stenography 35, Francis Bacon Biographical 39, Ciphers 46, Cyphars in Advancement of Learning 49, Cyphars in De Augmentis 50, Bi-literal Cipher Plan and Illustration 51, facsimiles 55–72, Method of Cipher in Novum Organum 73, Publisher’s Note 76, Quarto title pages 85. The classification statement is on page 2, in the “Personal” section, and reads in part that the distinguishing features in the small letters “have been more difficult to classify” and that study was required to “educate the eye to distinguish them.” No feature is named anywhere in Part I.
⚑ Riverbank’s five, as measurements
larger      ->  overall size of the letter
rounder     ->  curvature of the bowl
more upright->  slant
more robust ->  stroke weight
longer tail ->  length of the flourish
Taken from Hints pp. 9–10. All five were planted and tested; the project’s earlier focus on slant alone followed from reading rule 5, which is explicitly about circular letters, as though it governed every letter.
⚑ The corpus
Tesseract 5.3.4 at --psm 6 supplies word and character boxes; letter identities come from the project’s own transcription, never from Tesseract’s reading. A word is accepted only where its box count equals the known spelling length. That yielded 183 candidate b from 42 pages. Binarization is Niblack k=−0.25, window 35, chosen by calibration: every crop is known to be a b and a b has one counter, so the right threshold is the one leaving a single counter open on the largest share. Measured over 183 — Niblack 82.0%, Otsu 74.9%, Sauvola k=0.12 62.8%.
The transcription records 203 lower-case b in all 431 wholly-italic lines on these pages, so the extraction took 183 of 203 available — 90%. That number ended a separate line of work; see failures below.
⚑ Two screens, cross-tabulated
Each glyph is scored against Riverbank’s own a-form and b-form b from Keys p. 39, kept on the better of the two and never on the difference — filtering on the difference would pre-select a corpus shaped like their claim. Independently, a geometry screen tests proportion and the enclosed white of the counter.
                    geometry keeps   geometry rejects   total
Riverbank keeps          151               25             176
Riverbank rejects          2                5               7
total                    153               30             183
They fail in opposite directions: heavy inking closes the bowl and defeats the counter test, light inking defeats the overlap test. The median gap between the two Riverbank exemplars’ scores is 0.016, so whole-glyph overlap carries almost no form information — which is exactly what makes it safe as an “is this a b” gate.
A third screen rejects glyphs carrying ink that is not part of the letter: in a sound b the top half of the bounding box holds 31–44% of the ink, and requiring no more than 46% flags exactly four, each with a stroke from the line above welded to it. Final corpus 174, with a 149-glyph core whose bowls are all measurable.
⚑ The separation test
Glyphs are registered to a 56×34 frame by height, centered on the ink centroid, lightly blurred, reduced by SVD to 18–24 components. Projection pursuit then hill-climbs a unit direction to maximize Hartigan’s dip, with 70–220 random restarts.
The discipline is the whole of it: fit on half the glyphs, score on the other half. Any search over enough directions finds a bimodal one in noise, so the winner’s own score is not evidence. A direction describing a real property still separates glyphs it was not fitted to; one that fitted noise does not. The held-out score is compared against 150–200 randomly chosen directions scored identically.
real corpus, nothing planted
  12 splits   detected 0   held-out dip 0.0294
  24 splits   detected 1   held-out dip 0.0310
  randomly chosen directions beat it in 62% of draws
⚑ What the instrument can see
Each characteristic planted into a random half of the real glyphs at known magnitude, the search never told which or whether. Detections out of 8 independent splits:
size        14%  8/8     10%  8/8      7%  6/8      4%  1/8
flourish    30%  8/8     20%  7/8     13%  6/8      8%  0/8
slant        8d  8/8      6d  7/8    4.5d  1/8
weight      60%  2/8
roundness   55%  1/8
So for three of the five, the corpus bounds any real difference below 7% in size, 13% in tail length and 6 degrees of slant.
⚑ The blind spot, and why it is a representation fault
Weight and roundness do not register at any magnitude tried. A 60% change in stroke mass — far past anything that could pass unnoticed on a page — is detected twice in eight splits, barely above the one-in-twenty a wrong answer earns by chance.
The cause is in the pipeline, not the Folio. Registering to a common height normalizes size and weight information away before the search begins, and no linear projection over pixel values can express curvature. To test “more robust,” ink mass must be carried as an absolute per-glyph quantity alongside the printing density of its source page, not normalized out. To test “rounder,” the measurement has to be on the traced contour — curvature along the outline, or the counter’s deviation from a fitted ellipse. Neither is a matter of more glyphs.
⚑ Filters proposed and rejected, with the measurements
Ink weight relative to the Riverbank mean. Proposed as a way to drop spills and smears. The 24 heaviest glyphs turned out to be clean, well-formed b’s that were simply printed heavily; the measure runs 0.75 to 2.39 with no gap, and the Folio median sits 22% above Riverbank — a fact about two printings. Rejected, and doubly so: relative darkness is one of the characteristics under test, so screening on it would prejudge the question.
A maximum on the counter. Among glyphs that have a counter the measure is bunched between 9.7% and 12.2% of the bounding box, with no upper tail, and the 16 largest counters belong to the sharpest-printed letters in the set. A ceiling would discard the best evidence first. The real residue is a minimum: 16 glyphs have no measurable bowl.
Dilating the Riverbank masks. Tried at ±1, 2 and 3 pixels, on the template alone and on both sides. After the contour fix every variant returns identical recall, 151/153; only the scale moves, the median rising from 0.69 to 0.85 with the gate rising to match. Inert, and abandoned.
Re-attaching broken strokes on row overlap. Worse than the rule it replaced — it pulls in the neighboring letter. Rejected on sight of the comparison figure.
⚑ Three things this project had wrong
The contour rule. The binarizer kept the largest blob of ink and re-attached any fragment overlapping its columns. Italic letters always overlap in x, so the test admitted descender tails from the line above and specks below the baseline. Keeping one component and nothing else cleans seven of the nine affected glyphs; the two it damages are caught downstream. Two crops previously counted as merged pairs proved not to be merges at all.
The template threshold. Set at 0.50 by eye. The merged pairs score at most 0.325, so the gate belongs at 0.35 — a measured value. The old setting was discarding real letters for nothing.
Dropping the Riverbank screen entirely. It was briefly removed on the grounds that the two exemplars score within 0.016 of each other and so carry no form information. That reasoning was backwards: the near-identical scores are precisely what make the mask form-neutral and therefore safe. It was restored, and it catches every merged pair on its own.
⚑ A correction to this project’s earlier framing
Earlier work here treated the pitch or slant angle as the discriminator to test, and reported a battery of eleven hand-designed measurements as though they covered the claim. Reading Hints directly shows that slope is Riverbank’s rule for circular letters; for a long-tailed letter such as b their rule names slope and flourish length, and their general rule names size, roundness and weight besides. The earlier framing tested roughly one fifth of what was claimed. Today’s battery is the correction.
⚑ Failures and dead ends
line segmentation, attempted twice, abandoned
  threshold on full image width  -> 18 lines where 59 exist, one band 427px tall
  threshold on block ink         -> 41 lines where 29 exist
  resolved by not segmenting lines at all: the alignment files
  already record every line position, and strips render at
  exactly 4.00x the alignment frame

psm 7 on pre-cut lines, tested and abandoned
  line coverage   56% -> 94%     a real improvement
  b extracted     183 -> 70      a much larger loss
  the ceiling measurement ended it: only 203 b exist in these
  lines, so the old whole-page pass was already taking 90% of
  everything available. nothing left to win.

glyph cutting, two rules discarded before the present one
  x-overlap merge   glued adjacent letters together
  column minima     cut through letters

archive.org refused direct fetch from both shells and from the
  full-text API; worked around via the browser extension
⚑ Environment
Tesseract 5.3.4. Python with NumPy, SciPy, scikit-image, Pillow; diptest 0.11.0 for Hartigan’s dip. Chromium via Playwright for PDF rendering. Folio page images from the Bodleian scans held in the project archive. Corpus, screening criteria, the planted-characteristic battery and every script named above are published with this issue, so each figure can be recomputed rather than taken on trust.
⚑ Publication
GitHub Pages from the repository root, no build step, no framework, no analytics, no trackers and no cookies. The custom domain baconian-ciphers.online resolves through four A records at the apex to GitHub’s addresses, with www a CNAME to the Pages host; TLS is issued automatically by Let’s Encrypt and HTTPS is enforced. All internal links are relative, so a change of domain touches one file. Total infrastructure cost is about a dollar a year — chosen deliberately, so that nothing here depends on a service that can withdraw it. Issues are superseded, never deleted: a link sent today will resolve next year.